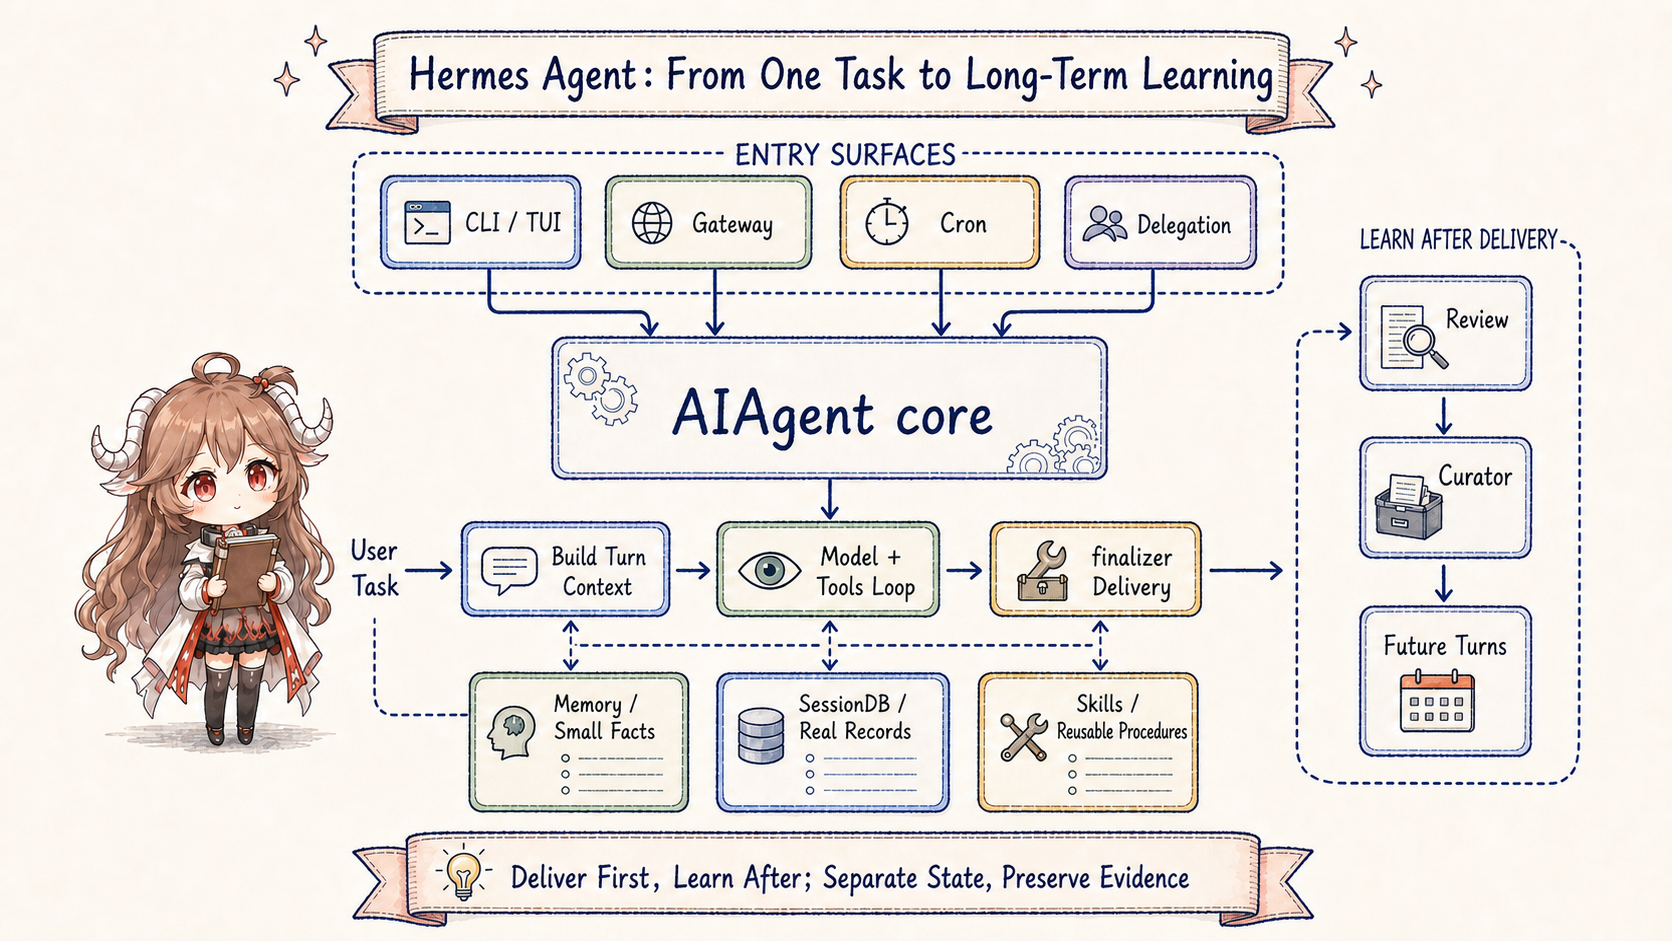
Start with an ordinary coding session. You ask an agent to change a repository. It reads the README and project rules, searches the code, edits files, and runs tests. A test fails, so it inspects the log, adds an edge case, and runs again. In the middle you say, "For this project, do not edit generated files directly." Later you ask it to find the failed command from earlier.
For a short chat, the easy answer is to append every message to history and send the whole history back to the model. A long-running agent runs into pressure quickly: history expands, tool output overwhelms the task, user preferences get mixed with one-off failures, and different task entry points begin to disagree. The CLI remembers one thing, the gateway remembers another, and a cron job cannot ask the user a follow-up.
A useful first definition is that Hermes Agent is a task runtime wrapped around a model. The model decides what should happen next. Tools read files, edit code, and run commands. Hermes assembles the user's request, project rules, and tool results into work that can continue, recover, and be audited. In this article, runtime means that coordinating layer around the model and its tools.
Hermes Agent describes itself in the README feature map as a self-improving agent. It can work through terminals and messaging gateways, run scheduled jobs, delegate work, and preserve lessons from completed tasks. Those capabilities orbit one simpler question: how should an agent keep the current task, durable history, long-term knowledge, and background learning in their proper places?
Reading goal. The whole article follows one task: fix a failing test. By the end, you should be able to replay where a turn begins and ends, how the model and tools hand work back and forth, why the durable record differs from the model's working copy, and which handoffs the next six articles will examine in detail.
Source scope. This article uses the public README, configuration, and a fixed source
snapshot. Direct claims come from linked source. Design intent is inferred only where call chains, data
shapes, or comments support it. README is the map; source is the mechanism. For example, the visible
session_search path uses SQLite/FTS5 and returns real message windows without another LLM call
inside the tool.
We will not begin with "self-evolution." This article follows one instruction through its different locations and replays a complete turn; later chapters separate standing rules, history, and background learning. Once that route connects, "self-evolving" stops sounding like a vague slogan. It becomes a state discipline: deliver the current task first, write reusable material into the right store afterward, and let future turns retrieve it according to source, lifetime, and risk.
1. Why one sentence has to pass through four places
Keep following the sentence from the opening: "Do not edit generated files in this repository." It looks like one user message. For an agent to use it correctly, however, the sentence has to pass through four places. Ignore the source names for a moment and watch the job it performs in each place.
The first place is the door. The sentence may arrive from a terminal, a gateway, or a scheduled job. The door receives the task and hands it to the shared turn lifecycle. If every entry point assembles its own rules and stores its own history, one agent soon behaves like several unrelated assistants.
The second place is the workbench for this turn. Before calling the model, the runtime combines the user's words with project rules, available tools, and material recalled for this task. The model needs to see "do not edit generated files" and may also need a list of files produced by the generator. That list is temporary runtime context; it must not masquerade as something the user said.
The third place is the record. The original user message, the answer, and the actual tool calls and results are stored in order. If the user later asks what they said, the system should recover evidence rather than a model's paraphrase. This record also has to be written early instead of waiting for the whole task to succeed.
The fourth place is experience for future tasks. After foreground inference, a background path may decide whether the sentence expresses a stable preference worth preserving. If it was a one-off constraint, that path may write nothing. Receiving a sentence, showing it to the model now, preserving that it happened, and deciding whether to reuse it later are connected steps, but they are not one operation.
Now the source vocabulary has a concrete hook. The source calls the door an entry surface, meaning a task entry point; the workbench
is the model view; the record is the real transcript; turn-finalization
distillation happens in background review, whose result may enter durable state.
AIAgent sits between them because every entry point returns
to one turn lifecycle instead of maintaining a separate brain.
| Place | Role in the example | Typical failure |
|---|---|---|
| Task entry point | Receive the instruction from a terminal, gateway, scheduled job, or delegated task. | Each entry builds context differently and behavior diverges. |
| Model view | Assemble the user's words, rules, tools, and temporary context into a working copy. | Transient recall leaks into stable prompt and breaks cache discipline. |
| Real transcript | Store the original message, answer, tool calls, and tool results in order. | Summaries replace raw evidence, making later recovery brittle. |
| Background review | Decide after foreground inference which facts or procedures deserve reuse in future tasks. | Preferences, evidence, and procedures collapse into one vague memory. |
The table is only a compact replay. It separates preserving raw evidence from distilling future experience; the next article will place those responsibilities in SessionDB, Memory, and Skills. In the opening figure, direction matters more than node count: entry points do not write long-term knowledge directly, and background review does not compete with the foreground answer.
2. Walk one repair task through a complete turn
Now run the task from the opening. You say, "Fix this failing test." Hermes eventually answers, "I changed two files and the test now passes." Everything from receiving the user message to delivering that answer is one turn. A turn is not one model call. The model may first request files, inspect their contents, request an edit, run a test, and react to another failure. Hermes owns that whole lifecycle rather than any single decision inside it.
A naive implementation saves history only after everything succeeds. A model error, stuck tool, or process exit can then erase the turn. Hermes instead makes four stages visible: receive and preserve the task, prepare what the model should see, let the model and tools hand work back and forth, then deliver the answer and distribute state. Follow them in order.
2.1 Receive the task: build the workbench and preserve the request
When the message arrives, Hermes first creates a workbench for this turn. It restores the prior session, identifies project rules and available tools, assigns turn identifiers, and persists the user's original words early. If a later model call fails, the system still knows what the user requested and where recovery should begin.
The source names now have a job to attach to. The foreground entry is
run_conversation,
and per-turn setup lives in build_turn_context. Its
TurnContext
carries the messages, standing prompt, identifiers, and prefetched context used later in the turn. The
_persist_turn_start path
means that a successful answer is not a prerequisite for preserving the request.
2.2 Prepare the first model call: copy a working view from the record
The durable record is not identical to what the model needs for its next decision. The record should keep the user's words and events that really occurred. For this repair, however, the model may temporarily need a list of generated files or plugin-supplied project guidance. Hermes copies the real messages into a working view and attaches that temporary material to the copy.
That working copy is the model view; the durable record is the transcript.
Before a provider call, Hermes copies messages and adds external recall and plugin context only to the API
copy of the current user message. It leaves the original list unchanged. The transition is visible in
compose_user_api_content.
Without the copy, a later turn could not reliably distinguish user evidence from temporary runtime help.
2.3 Let the model and tools hand work back and forth
Only now does Hermes call the model. The model does not directly open a file or run a test; it returns a request naming a tool and its arguments. Hermes checks and executes that request, appends either the result or the error to the turn in order, and gives the updated working view back to the model. The model then chooses again: request another tool, or produce the final answer when it has enough evidence.
A turn therefore contains a smaller loop that may repeat several times. The source loop begins at the
turn budget and while condition.
The tool layer executes calls and returns results in the model's original order, an invariant stated in
tool_executor.py.
In the running example, the exchange reads naturally:
User: Fix this failing test
Hermes: Preserve the request and prepare project rules and tools
Model: Read the test and the related implementation
Hermes: Run the read tools and append their results
Model: Edit the implementation and run the test
Hermes: Run the tools and append success or failure
Model: The evidence is sufficient; return the final answer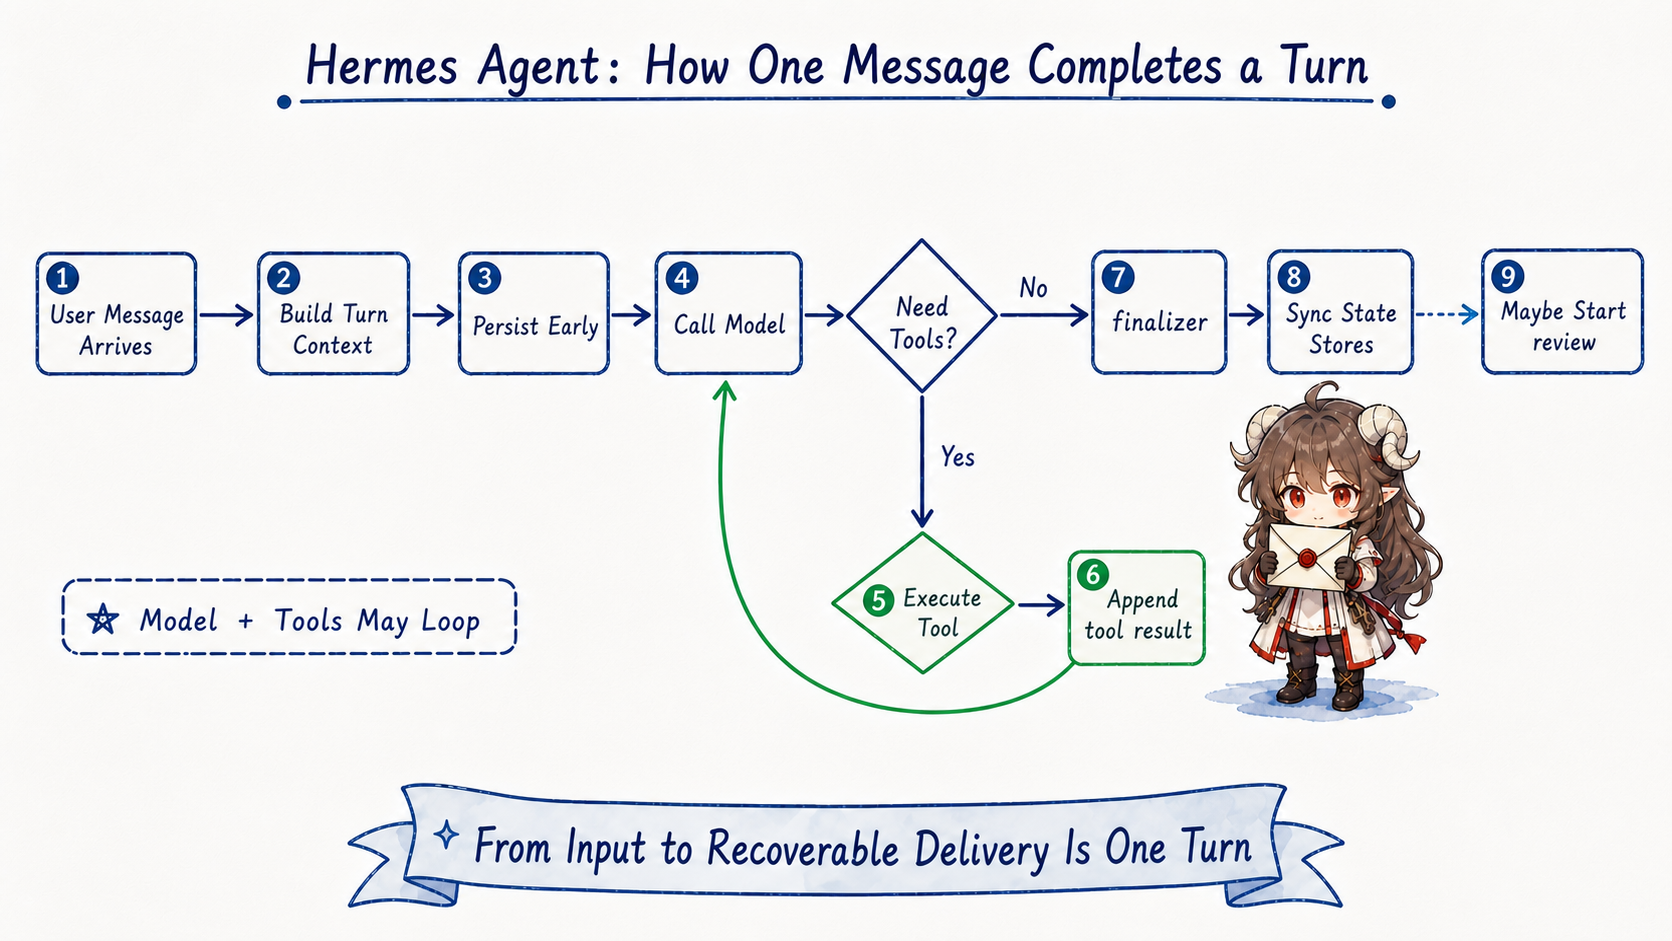
2.4 Finalization separates response text, completion, and delivery
After the model stops requesting tools, the finalizer shapes real messages, persists the session, and builds the return value.
Response text does not prove completion: interruption, failure, or budget exhaustion can still leave text worth displaying.
Callers must inspect completed, failed, and interrupted. These describe the core turn; they prove neither passing tests nor channel delivery. Failed cleanup steps can also return cleanup_errors; callers must not overlook a persistence failure just because answer text exists.
The finalization tail synchronizes external memory, then starts background review when a response exists, the turn was not interrupted,
review is enabled, and the counters qualify. Review receives a message snapshot and does not hold the foreground model loop open.
Its spawn call still occurs before finalize_turn returns. “Learning after delivery” is therefore a responsibility split, not a guarantee that every CLI, Gateway, or API response has reached its destination before the thread starts. Review may write nothing.
Model stops its tool loop → finalizer determines completed / failed / interrupted
                         → shapes and persists records
                         → synchronizes state and conditionally starts review
                         → returns a result for the entrance to deliver
Review completion and channel delivery are observed separately
The replay is preserve the request → assemble the model view → iterate with tools → finalize and return → deliver through the entrance. Review is a conditional side path; Curator is separate periodic maintenance. The next chapter separates prompt and state, and chapter three explains the background triggers. Later Skill creation, evaluation, and adoption all depend on keeping generated text, validation, and adopted changes distinct.
3. Tool calls are not the model's private business
Tool calling can look like "the model asks for a tool and the tool runs." Hermes puts more runtime around
that moment. The executor separates concurrent and sequential paths; the concurrent path preserves original
tool-call order while appending results, and the sequential path handles stricter interaction cases. The
relevant code starts around
execute_tool_calls_concurrent
and
the sequential path.
Mixed batches also use segmented execution: parallel and sequential segments preserve original order and barriers. Results remain in call order. This does not start every tool at once; failed persistence prevents later segments from advancing without durable records of earlier actions.
The more important question is which component supplies state at execution time. session_search needs SessionDB,
memory needs the built-in memory store and external-provider sync, and
delegate_task needs the agent's delegation dispatcher. That dispatch is visible in
inline_tool_executors.py.
Remove middleware, timing, and display concerns, and the responsibility split becomes visible:
if function_name == "session_search":
    db = agent._get_session_db_for_recall()
    result = session_search(..., db=db)
elif function_name == "memory":
    result = memory_tool(..., store=agent._memory_store)
elif function_name == "delegate_task":
    result = agent._dispatch_delegate_task(function_args)
The model supplies only function_name and arguments. The current session database, authoritative
memory store, and parent task's delegation dispatcher are bound at execution time. The model cannot supply an arbitrary database object. History queries may name supported session or profile selectors, but the tool implementation resolves and opens them.
The model may request a tool, but the runtime decides which state it uses, how it is audited, which permissions apply, and how failures recover. Without that split, a temporary observation could become long-term memory, a search could guess at past history instead of reading evidence, and delegated work could contaminate the parent context.
4. Multiple task entry points share the core, but not every permission
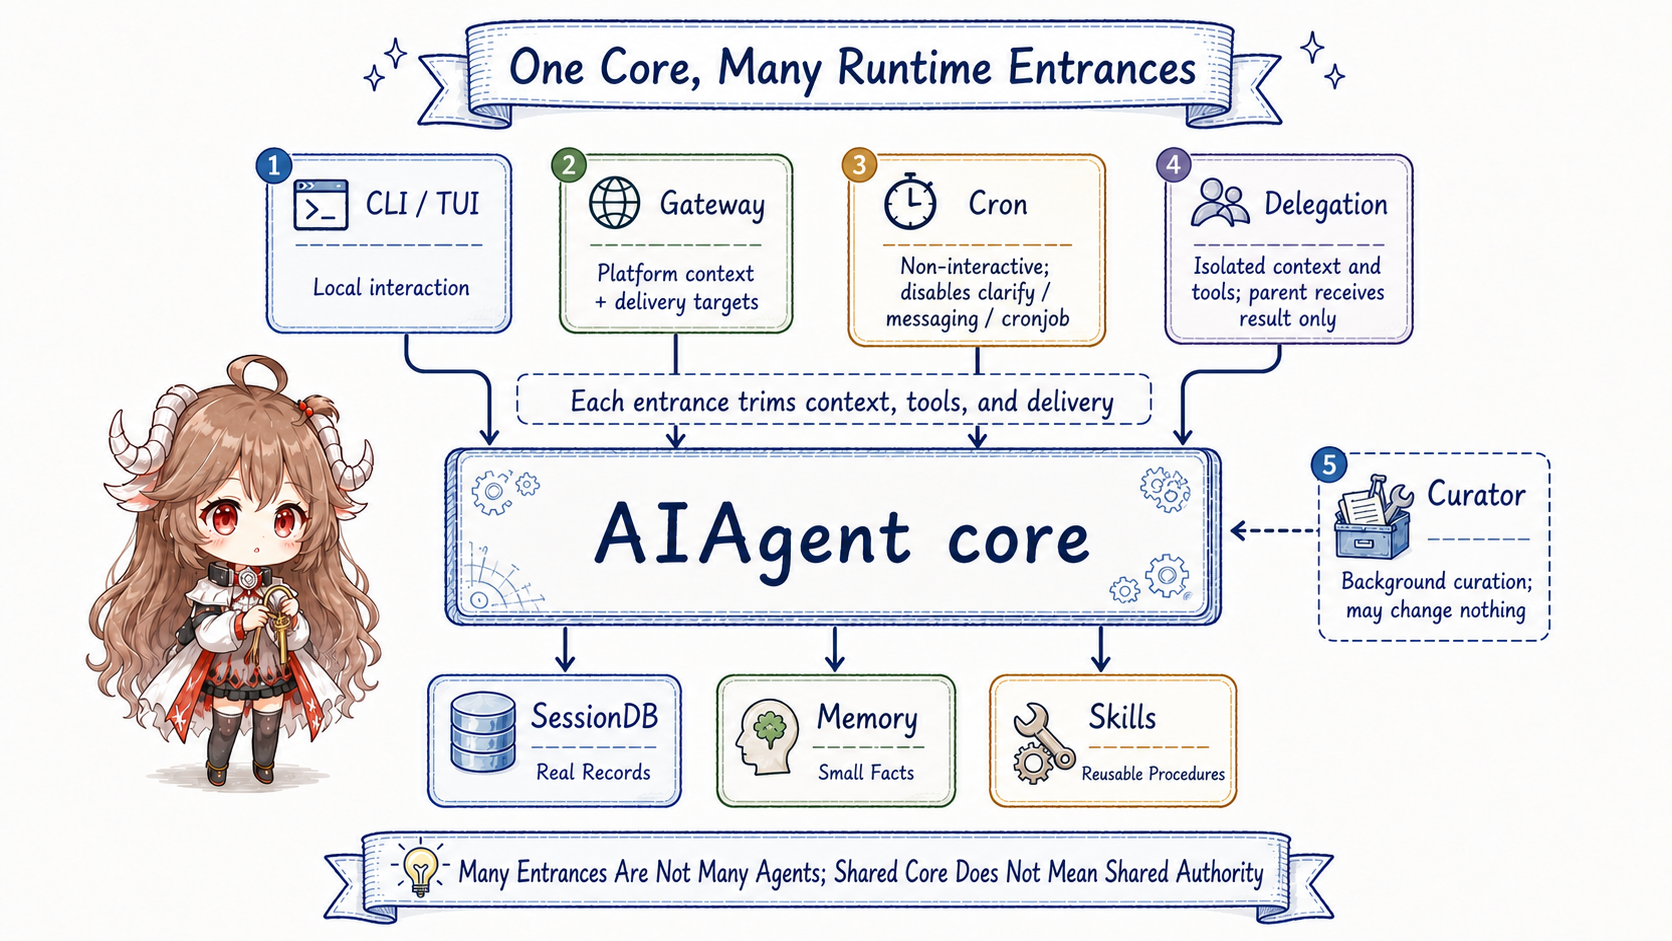
Hermes is not only a CLI. The source also includes gateway, cron, and delegation paths. If each entry point owned its own agent loop, information management would fragment. Hermes instead routes them toward the same core while narrowing each entry point's permissions.
4.1 Gateway supplies platform context to the shared core
SessionContext carries platform, user, channel, thread, and delivery details;
build_session_context_prompt renders the session section.
Gateway reuses or constructs an agent for the session, supplying model, runtime, tools, platform identity, and SessionDB in
the construction path, then calls agent.run_conversation.
4.2 Cron narrows tools because no one is there to answer
Cron always disables messaging and clarify. The scheduler also disables cronjob by default,
but cron.allow_agent_scheduling=true can lift that restriction alone. Configured disabled toolsets still apply.
Preventing recursive scheduling by default is not an unchangeable security boundary.
A no_agent job bypasses AIAgent and runs the script directly, delivering stdout or an error where appropriate.
Agent jobs scan the assembled prompt again after runtime Skill content and script output have been included.
4.3 Delegation acknowledges dispatch before reporting a result
Children still have isolated context, restricted tools, and independent task identifiers; the parent does not absorb their reasoning or full tool stream.
Waiting has changed: model-facing dispatch runs top-level delegation in the background and first returns status="dispatched".
The parent can do independent work, end its current turn, and resume when a completion message re-enters the conversation.
Acceptance is not successful completion.
{"status": "dispatched", "mode": "background", "count": 2, "delegation_id": "example-batch"}
This receipt shape omits goals and control handles. The default batch joins all children and returns one consolidated message.
Only an explicit delegation.independent_completions setting splits completion units by group or ungrouped task.
Nested orchestrators wait synchronously for workers within their own turn; direct Python calls also default to synchronous execution.
Missing asynchronous delivery support or exhausted capacity can fall back to synchronous work.
DELEGATE_BLOCKED_TOOLS includes delegate_task, clarify, memory, send_message, and cronjob_manage.
Configuration and depth budget determine whether a child can delegate further; claiming the orchestrator role does not grant that authority.
Child construction retains skip_context_files=True, skip_memory=True, and a fresh iteration budget.
Each child opens its own connection to the same database file so the parent's cleanup cannot close storage underneath a running background child.
5. Return to the practical question: where should information live?
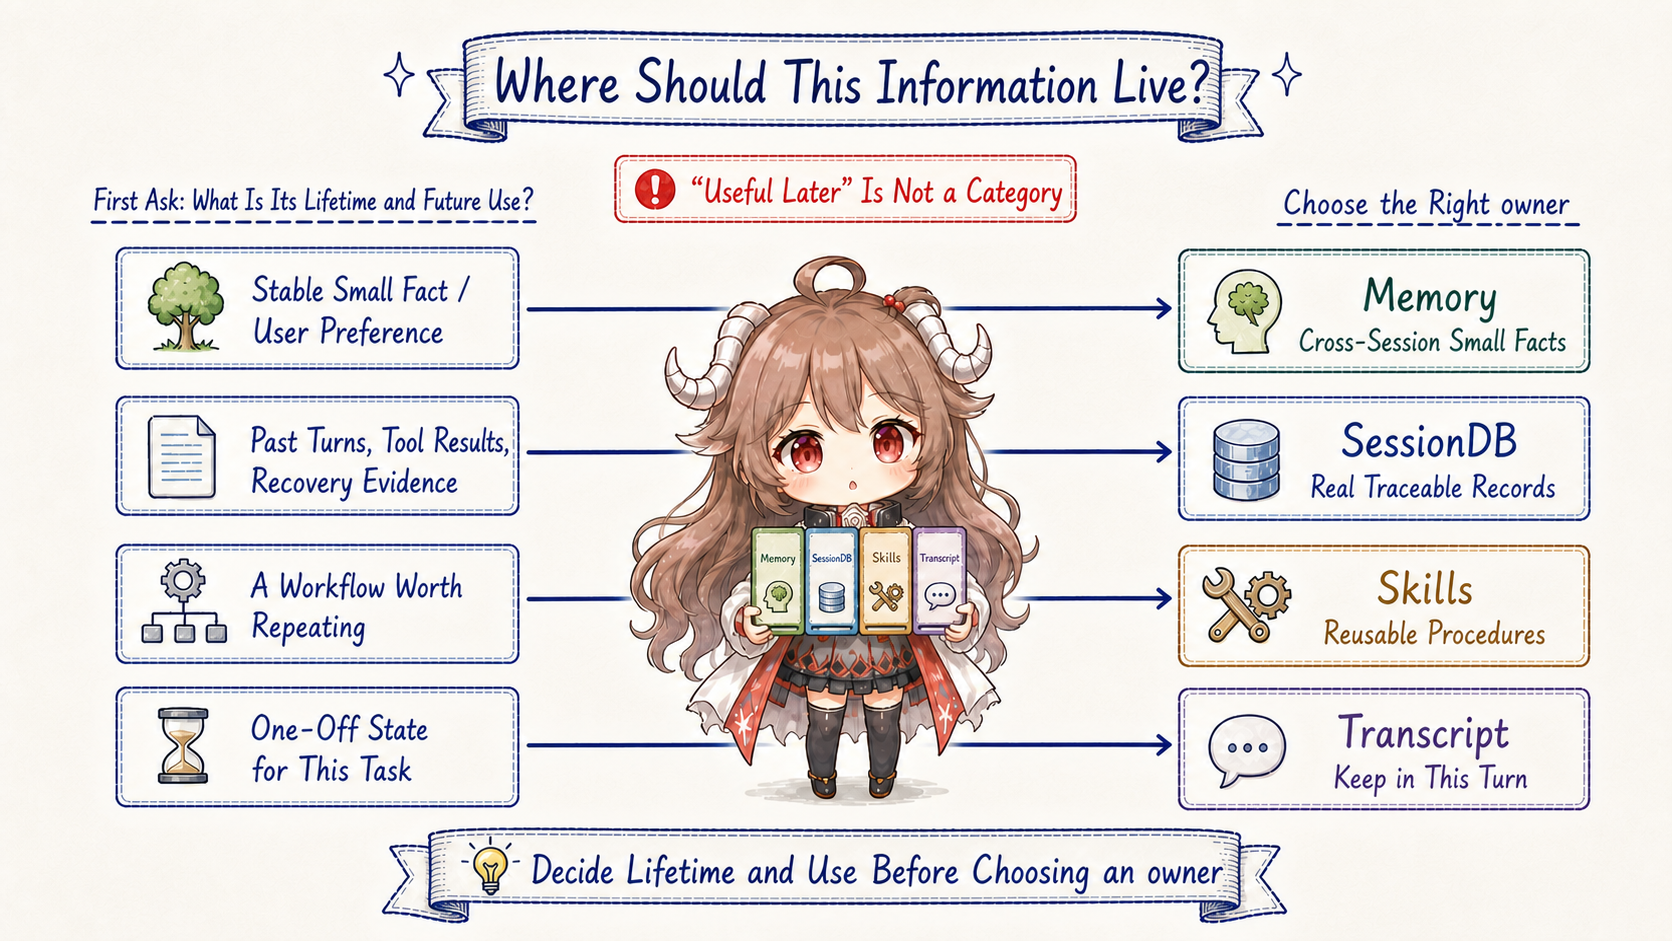
The opening scenario now has a concrete answer. A user preference, a failed command, a long tool output, a reusable process, and a temporary task state are not all "memory." Hermes first classifies the information, then decides which store should hold it and when the model should see it again.
| Information | Home | Reason | If misplaced |
|---|---|---|---|
| Cross-task user preference or stable environment fact | Memory | Applicable to every session; task-specific lessons belong in a Skill. | If left only in transcript, it may be hard to find later. |
| Past tool output or full conversation evidence | SessionDB / session_search | The real message window matters more than a summary. | If written to memory, one-time evidence becomes a fake rule. |
| Reusable method for future tasks | Skills | Procedural memory needs an index, body, and patch semantics. | If written as memory, the model gets a conclusion but not a process. |
| Current task progress, temporary failures, exploration | Transcript only | Useful for recovery, but not stable enough to harden. | If saved too early, future tasks inherit false constraints. |
5.1 Four common misreadings
First, memory is not the home for all history. Memory has budgets, scans, frozen snapshots, and manual semantics. Session search is the path for real past evidence.
Second, skills are not "one experience note per task." The skill system emphasizes class-level workflows, patching existing skills, and support files.
Third, background review is separate from the main answer, and spawning its thread does not prove channel delivery. The finalizer starts conditional review after constructing the response; review completion and delivery require separate evidence.
Fourth, cron is not ordinary chat automation. Cron narrows interactive tools, assembles prompt context differently, and supports a no-agent script path. Non-interactive entry points need stricter defaults.
6. Conclusion: self-evolution is state discipline, not the word "reflection"
The value in Hermes Agent's source is not the number of feature names attached to "self-evolving." It is the way the runtime separates the kinds of state that long-running agents usually blur: current turn, model view, durable transcript, small facts, searchable history, procedural skills, background review, idle curator, and per-entry-point policy.
A reader new to Hermes only needs to keep one sentence: an agent's long-term capability is not remembering everything, but knowing when each kind of information should appear, in which view, and whether it should be written down after the turn ends.
Facts should be small
and auditable.
Evidence stays in transcript.
Workflows become skills.
Current-turn recall does not
pollute the stable prompt.
Background review does not block
the foreground model loop.
Confirm channel delivery separately.
That is the reusable lesson: do not keep stretching one giant prompt. Define which component handles each state, how long it lives, and how it can be recovered. The hard part of a long-running agent is keeping information with different lifetimes from being confused.
Before asking how to improve a Skill, however, we need a more basic distinction: why should a user preference, a project rule, historical evidence, and a reusable procedure not all become "memory"? The next article keeps the same repair task and places the system prompt, Context, Memory, SessionDB, and Skills back under the components responsible for them. Evolution can only be precise after we know which object is actually changing.
Source references
- Fixed source snapshot: NousResearch/hermes-agent
- README feature map
- run_conversation entry
- TurnContext and turn prologue
- concurrent execution and ordered results
- runtime-owned tool dispatch
- finalizer state sync and review trigger
- gateway SessionContext
- tools disabled for cron
- delegation architecture note